Approximate differential privacy Dwork et al. (2006), also called -differential privacy, has the following definition:
The new privacy parameter, , represents a “failure probability” for the definition. With probability , we will get the same guarantee as pure differential privacy; with probability , we get no guarantee. In other words:
With probability ,
With probability , we get no guarantee at all
This definition should seem a little bit scary! With probability , anything at all could happen - including a release of the entire sensitive dataset! For this reason, we typically require to be very small - usually or less, where is the size of the dataset. In addition, we’ll see that the -differentially private mechanisms in practical use don’t fail catastrophically, as allowed by the definition - instead, they fail gracefully, and don’t do terrible things like releasing the entire dataset.
Such mechanisms are possible, however, and they do satisfy the definition of -differential privacy. We’ll see an example of such a mechanism later in this section.
Properties of Approximate Differential Privacy
Approximate differential privacy has similar properties to pure -differential privacy. It satisfies sequential composition:
The only difference from the pure setting is that we add up the s as well as the s. Approximate differential privacy also satisfies post-processing and parallel composition.
The Gaussian Mechanism
The Gaussian mechanism is an alternative to the Laplace mechanism, which adds Gaussian noise instead of Laplacian noise. The Gaussian mechanism does not satisfy pure -differential privacy, but does satisfy -differential privacy. According to the Gaussian mechanism, for a function which returns a number, the following definition of satisfies -differential privacy:
where is the sensitivity of , and denotes sampling from the Gaussian (normal) distribution with center 0 and variance . Note that here (and elsewhere in these notes), denotes the natural logarithm.
For real-valued functions , we can use the classic Gaussian mechanism with values of equal to or less than 1, a range called "high privacy"Balle & Wang (2018). This is in contrast to the Laplace mechanism, which can be used in any privacy regime, high or low.
It’s easy to compare what happens under both mechanisms for a given value of .
Source
epsilon = 1
vals_laplace = [np.random.laplace(loc=0, scale=1/epsilon) for x in range(100000)]

delta = 10e-5
sigma = np.sqrt(2 * np.log(1.25 / delta)) * 1 / epsilon
vals_gauss = [np.random.normal(loc=0, scale=sigma) for x in range(100000)]

plt.hist(vals_laplace, bins=50, label='Laplace')
plt.hist(vals_gauss, bins=50, alpha=.7, label='Gaussian');
plt.legend();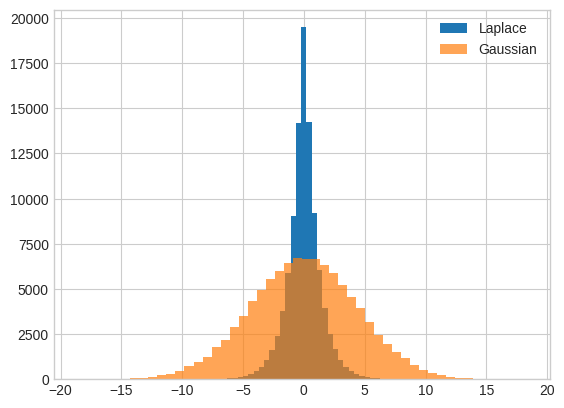
Here, we graph the empirical probability density function of the Laplace and Gaussian mechanisms for , with for the Gaussian mechanism.
Compared to the Laplace mechanism, the plot for the Gaussian mechanism looks “squished.” Differentially private outputs which are far from the true answer are much more likely using the Gaussian mechanism than they are under the Laplace mechanism (which, by comparison, looks extremely “pointy”).
So the Gaussian mechanism has two major drawbacks - it requires the use of the the relaxed -differential privacy definition, and it’s less accurate than the Laplace mechanism. Why would we want to use it?
Vector-Valued Functions and their Sensitivities
So far, we have only considered real-valued functions (i.e. the function’s output is always a single real number). Such functions are of the form . Both the Laplace and Gaussian mechanism, however, can be extended to vector-valued functions of the form , which return vectors of real numbers. We can think of histograms as vector-valued functions, which return a vector whose elements consist of histogram bin counts.
We saw earlier that the sensitivity of a function is:
How do we define sensitivity for vector-valued functions?
Consider the expression . If is a vector-valued function, then this expression represents the difference between two vectors, which can be computed as the difference between their corresponding elements (the difference of two length- vectors is thus a new length- vector). This new vector is the distance between and , represented as a vector.
The magnitude of this vector is the sensitivity of . There are several ways to compute the magnitude of a vector; we’ll use two of them: the norm and the norm.
L1 and L2 Norms
The norm of a vector of length is defined as (i.e. it’s the sum of the vector’s elements). In 2-dimensional space, the norm of the difference between two vectors yields the “manhattan distance” between them.
The norm of a vector of length is defined as (i.e. the square root of the sum of the squares). In 2-dimensional space, this is the “Euclidean distance”, and it’s always less than or equal to the norm.
L1 and L2 Sensitivities
The sensitivity of a vector-valued function is:
This is equal to the sum of the elementwise sensitivities. For example, if we define a vector-valued function that returns a length- vector of 1-sensitive results, then the sensitivity of is .
Similarly, the sensitivity of a vector-valued function is:
Using the same example as above, a vector-valued function returning a length- vector of 1-sensitive results has sensitivity of . For long vectors, the sensitivity will obviously be much lower than the sensitivity! For some applications, like machine learning algorithms (which sometimes return vectors with thousands of elements), sensitivity is significantly lower than sensitivity.
Choosing Between L1 and L2
As mentioned earlier, both the Laplace and Gaussian mechanisms can be extended to vector-valued functions. However, there’s a key difference between these two extensions: the vector-valued Laplace mechanism requires the use of sensitivity, while the vector-valued Gaussian mechanism allows the use of either or sensitivity. This is a major strength of the Gaussian mechanism. For applications in which sensitivity is much lower than sensitivity, the Gaussian mechanism allows adding much less noise.
The vector-valued Laplace mechanism releases , where are drawn i.i.d. from the Laplace distribution with scale and is the sensitivity of
The vector-valued Gaussian mechanism releases , where are drawn i.i.d. from the Gaussian distribution with and is the sensitivity of
The Catastrophe Mechanism
The definition of -differential privacy says that a mechanism which satisfies the definition must “behave well” with probability . That means that with probability , the mechanism can do anything at all. This “failure probability” is concerning, because mechanisms which satisfy the relaxed definition may (with low probability) result in very bad outcomes.
Consider the following mechanism, which we will call the catastrophe mechanism:
With probability , the catastrophe mechanism satisfies -differential privacy. With probability , it releases the whole dataset with no noise. This mechanism satisfies the definition of approximate differential privacy, but we probably wouldn’t want to use it in practice.
Fortunately, most -differentially private mechanisms don’t have such a catastrophic failure mode. The Gaussian mechanism, for example, doesn’t ever release the whole dataset. Instead, with probability , the Gaussian mechanism doesn’t quite satisfy -differential privacy - it satisfies -differential privacy instead, for some value .
The Gaussian mechanism thus fails gracefully, rather than catastrophically, so it’s reasonable to have far more confidence in the Gaussian mechanism than in the catastrophe mechanism. Later, we will see alternative relaxations of the definition of differential privacy which distinguish between mechanisms that fail gracefully (like the Gaussian mechanism) and ones that fail catastropically (like the catastrophe mechanism).
Advanced Composition
We have already seen two ways of combining differentially private mechanisms: sequential composition and parallel composition. It turns out that -differential privacy admits a new way of analyzing the sequential composition of differentially private mechanisms, which can result in a lower privacy cost.
The advanced composition theorem Dwork et al. (2010) is usually stated in terms of mechanisms which are instances of -fold adaptive composition.
Iterative programs (i.e. loops or recursive functions) are nearly always instances of -fold adaptive composition. A for loop that runs 1000 iterations, for example, is a 1000-fold adaptive composition. As a more specific example, an averaging attack is a -fold adaptive composition:
# works for sensitivity-1 queries
def avg_attack(query, epsilon, k):
    results = [query + np.random.laplace(loc=0, scale=1/epsilon) for i in range(k)]
    return np.mean(results)

avg_attack(10, 1, 500)np.float64(10.017920091412918)In this example, the sequence of mechanisms is fixed ahead of time (we use the same mechanism each time), and .
The standard sequential composition theorem says that the total privacy cost of this mechanism is (in this case, ).
The advanced composition theorem says:
import numpy as np
import matplotlib.pyplot as plt

# Fixed parameters
epsilon = 0.1          # base epsilon
delta = 1e-5           # base delta for each mechanism
delta_prime = 1e-6     # additional delta for advanced composition

# Range of composition depths
k_values = np.arange(1, 201)

# Advanced composition epsilon'
def advanced_composition(eps, k, delta_prime):
    term1 = np.sqrt(2 * k * np.log(1 / delta_prime)) * eps
    term2 = k * eps * (np.exp(eps) - 1)
    return term1 + term2

eps_advanced = advanced_composition(epsilon, k_values, delta_prime)

# Naive composition epsilon'
eps_naive = epsilon * k_values

# Plot
plt.figure(figsize=(8, 5))
plt.plot(k_values, eps_advanced, label='Advanced Composition', color='blue')
plt.plot(k_values, eps_naive, label='Naive Composition', color='red', linestyle='--')

plt.xlabel('Number of Compositions $k$')
plt.ylabel(r'Composed Privacy Budget $\epsilon^\prime$')
plt.title(r'Naive vs. Advanced Composition $(\epsilon=0.1, \delta=10^{-5})$')
plt.legend()
plt.grid(True)
plt.tight_layout()
plt.show()
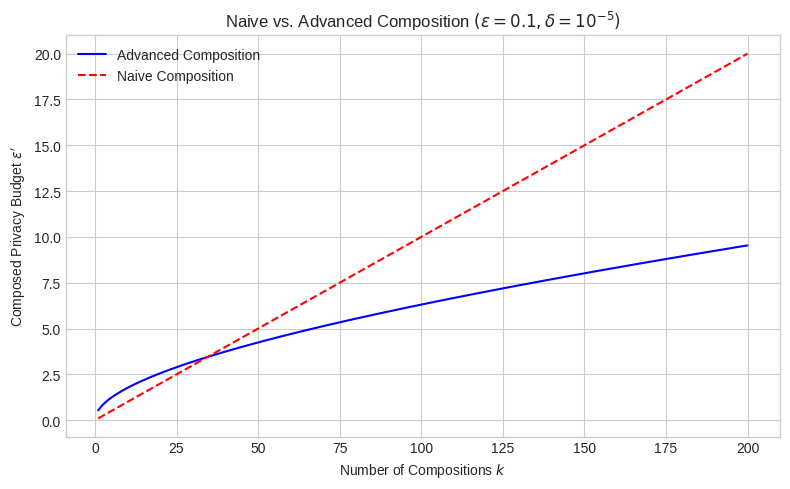
The red dashed line (naive composition) shows linear growth. The blue curve (advanced composition) grows more slowly due to sublinear behavior of the square root term. This demonstrates how advanced composition can significantly improve privacy accounting in multi-query settings.
So advanced composition derives a much lower bound on than sequential composition, for the same mechanism. What does this mean? It means that the bounds given by sequential composition are loose - they don’t tightly bound the actual privacy cost of the computation. In fact, advanced composition also gives loose bounds - they’re just slightly less loose than the ones given by sequential composition.
It’s important to note that the two bounds are technically incomparable, since advanced composition introduces a . When is small, however, we will often compare the s given by both methods.
Standard sequential composition, it turns out, beats advanced composition for smaller than about 37. Thus, advanced composition is only really useful when is large (e.g. more than 100). When is very large, though, advanced composition can make a big difference!
Advanced Composition for Approximate Differential Privacy
The description of advanced composition above requires the individual mechanisms being composed to satisfy pure -differential privacy. However, the theorem also applies if they satisfy -differential privacy instead. The more general statement of the advanced composition theorem is as follows (Dwork et al. (2010), Theorem 3.20):
The only difference is in the failure parameter for the composed mechanism, where we have an additional term. When the mechanisms being composed satisfy pure -differential privacy, then , and we get the same result as the statement above.
- Dwork, C., Kenthapadi, K., McSherry, F., Mironov, I., & Naor, M. (2006). Our Data, Ourselves: Privacy Via Distributed Noise Generation. In S. Vaudenay (Ed.), Advances in Cryptology - EUROCRYPT 2006 (pp. 486–503). Springer Berlin Heidelberg.
- Balle, B., & Wang, Y.-X. (2018). Improving the Gaussian Mechanism for Differential Privacy: Analytical Calibration and Optimal Denoising. In J. Dy & A. Krause (Eds.), Proceedings of the 35th International Conference on Machine Learning (Vol. 80, pp. 394–403). PMLR. https://proceedings.mlr.press/v80/balle18a.html
- Dwork, C., Rothblum, G. N., & Vadhan, S. (2010). Boosting and Differential Privacy. 2010 IEEE 51st Annual Symposium on Foundations of Computer Science, 51–60. 10.1109/FOCS.2010.12